Measure an AI assistant by completed customer tasks and business outcomes—not conversation volume alone
Use a small scorecard that connects what people ask, whether they receive a useful answer, what they do next, and the business result that follows.
To determine whether an AI assistant is helping, define one business problem, identify the visitor action that represents success, and review both conversation quality and downstream outcomes. Track useful answers, completed tasks, unresolved questions, qualified leads, escalations, and repeated knowledge gaps. Compare the results with a baseline, inspect real conversations regularly, and update the assistant’s information before expanding its role. OceSha AI supports a broader create-publish-engage-measure cycle, while Lumi serves as its AI Concierge.
- Begin with one measurable business problem, such as reducing repeated questions or helping visitors find the right information.
- Measure successful outcomes and unresolved needs; a high conversation count does not prove that the assistant is useful.
- Review actual conversations alongside numbers because a plausible answer can still be incomplete, outdated, or irrelevant.
- Connect assistant activity to a next step such as finding information, submitting a lead, or reaching the appropriate human.
- Treat measurement as a cycle: inspect results, improve the underlying knowledge, test again, and expand only after the first use case works.
Start with the business problem, not an assistant dashboard
OceSha AI is the self-service creation platform of OceSha Ventures, and Lumi is its AI Concierge. Measuring whether an assistant helps your business starts before either technology or analytics: describe the customer problem in plain language. “We want AI” is not measurable. “Visitors struggle to find accurate answers about our services” gives you a specific need, an audience, and an outcome to examine.
A useful AI assistant helps a visitor complete an intended task with accurate, relevant information and creates an observable improvement for the business. The task might be finding an answer, reaching the right resource, expressing qualified interest, or recognizing that human help is needed. The correct measure depends on the task—not on how impressive the conversation sounds.
Choose a narrow first use case. Write down the question or task, what a successful response looks like, and what should happen next. If the assistant is supposed to answer recurring questions, success means more than producing a response: the visitor should receive the information needed without repeatedly rephrasing the question. If you are still choosing a starting point, compare realistic first AI projects for a small business before defining the scorecard.
Measure the problem you hired the assistant to solve. Conversation totals, response length, and novelty are activity signals; they are not business outcomes by themselves.
Build a scorecard around outcomes, quality, and failure signals
A dependable scorecard combines three views. Outcome measures show whether the visitor completed the intended next step. Quality measures show whether the response was accurate, relevant, understandable, and grounded in current business information. Failure measures reveal unresolved questions, repeated attempts, abandonment, inappropriate answers, and cases that should have moved to a person sooner.
Do not reduce all of these signals to one number too early. A strong completion rate can conceal poor answers if the completion event is loosely defined. A low escalation rate can look efficient while hiding unsupported responses. Before customers encounter the experience, use a structured process for testing an AI assistant before launch, including common questions, ambiguous wording, missing information, and requests that belong with a person.
An assistant that responds often is not necessarily helping. Treat usage as context, then judge success through response quality, completed tasks, knowledge gaps, and business outcomes.
Establish a baseline and review evidence in the right order
A baseline answers a simple question: what happens without the assistant? Before launch, document how the selected task is currently handled. Note where visitors find information, which questions recur, when staff must intervene, and where people fail to reach the intended next step. You do not need a complex analytics program; you need a consistent reference point that can be compared with the same process after launch.
- Define one visitor task and one corresponding business objective.
- Describe the observable event that counts as successful completion.
- Capture the current experience so you have a baseline for comparison.
- Test representative questions and inspect the answers manually.
- Launch within a controlled scope rather than assigning every possible business question at once.
- Review outcomes, conversations, knowledge gaps, escalations, and visitor behavior together.
- Correct the underlying information, retest the affected questions, and compare the next period with the same baseline.
Review the evidence in that order. First ask whether the intended task was completed. Then inspect the answer that contributed to the outcome. Finally, look for patterns across conversations. This prevents a polished but inaccurate answer from being counted as success. It also keeps isolated unusual questions from distracting you from a recurring problem. For a simpler adoption path, use the simplest way to start using AI to keep the initial scope manageable.
Suppose a business wants an assistant to help visitors find information already approved by the business. The team defines success as reaching the correct information or the appropriate human route. During review, it groups unresolved questions, checks whether completed interactions used current information, and identifies where visitors asked the same thing repeatedly. The next improvement is not automatically a new feature; it may be clearer source material, better coverage of a recurring topic, or a more direct escalation path.
Conversation review matters as much as analytics
Numbers show patterns, but conversation review explains them. Read a representative selection of successful, unsuccessful, escalated, and abandoned interactions. Check whether the assistant understood the request, used the right business information, answered directly, and stopped appropriately when it lacked sufficient grounding. Look for answers that sound fluent but fail to resolve the task; these are particularly easy to miss in aggregate reporting.
- Quantitative review
- Reveals frequency, completion patterns, repeated failures, lead signals, and changes over time.
- Qualitative review
- Reveals why an answer worked or failed, whether its wording was appropriate, and what information was missing.
- Combined review
- Connects the business result to the conversation that produced it, making the next improvement more specific.
Tag recurring failure types consistently. Useful categories include missing information, outdated information, misunderstood intent, incomplete response, unclear next step, and unnecessary escalation. When the source material changes, update the assistant deliberately rather than waiting for failures to accumulate. A repeatable process for keeping an AI assistant current as your business changes is essential because measurement loses meaning when the assistant is evaluated against obsolete information.
The quality of measurement also depends on the quality of the source material. Separate approved facts from drafts, remove contradictions, and make ownership of updates clear. If you are preparing the source set, follow a deliberate method for giving an AI assistant the right business information. For teams without technical specialists, the important work remains defining the task, organizing trustworthy knowledge, reviewing answers, and deciding what needs human judgment; using AI without being a technical person explains that practical division of work.
Where OceSha AI and Lumi fit into the measurement cycle
The OceSha AI self-service creation platform lets users bring in knowledge from sources including documents, websites, text, audio, video, and other existing material. It uses that information to help create courses and content, publish and distribute content, educate learners, build a professional presence, engage an audience, and measure results. Its lifecycle is KNOWLEDGE → CREATE → PUBLISH → EDUCATE → ENGAGE → MONETIZE → MEASURE, with another documented loop of KNOWLEDGE → CREATE → PUBLISH → ENGAGE → MEASURE → CREATE AGAIN.
Within OceSha AI, one of Lumi’s primary capabilities is helping users navigate the platform. Authenticated guidance covers areas such as feature navigation, course creation, publishing, finding leads, viewing analytics, updating profiles, managing subscriptions, and choosing the appropriate platform area. This is informational and how-to guidance; the user still performs those actions. Recommendations can draw on information the user has provided so suggested content is relevant to the user’s knowledge, expertise, business, interests, and existing material.
OceSha AI’s training guide states that course activity contributes to analytics and performance information. That is useful within the broader content lifecycle, but course analytics should not be treated as a complete measurement system for every AI-assistant outcome. Apply the scorecard described above to the specific assistant task, and confirm which evidence is available for the experience you intend to evaluate. If website placement is part of the plan, first establish whether an assistant can be added to your website platform.
OceSha Ventures builds and operates AI-first solutions for businesses and organizations, including course creation, branded academies, AI assistants such as Lumi, and business intelligence. Users can also see real courses and branded learning experiences through OceSha Academy courses and academies. The distinction matters: OceSha AI supports self-service course and content creation, while branded academies and AI assistants are among the solutions built and operated by OceSha Ventures.
Before relying on any platform view as proof of assistant performance, confirm that it captures the task, outcome, and follow-up behavior that matter to your business. Platform activity is evidence only when it is connected to a clearly defined goal.
Decide whether to improve, expand, or stop
After each review, make one of three decisions. Improve the current use case when the objective is sound but answers or source material need work. Expand only when the initial task is consistently useful and the next use case has its own clear success definition. Stop or redesign the use case when the assistant cannot access reliable information, when human judgment is central to the task, or when the available evidence cannot show that the experience benefits visitors or the business.
Do not broaden the assistant simply because usage is increasing. Expansion creates more knowledge to maintain, more failure paths to inspect, and more outcomes to measure. Also distinguish a general-purpose conversational tool from an assistant designed around business knowledge and defined visitor tasks. The comparison between ChatGPT and a custom business AI assistant helps clarify which approach matches the job.
A sound next step is to write a one-page measurement brief containing the problem, audience, successful task, baseline, review schedule, escalation rule, and owner for knowledge updates. Then test the smallest version that can produce meaningful evidence. To discuss how OceSha’s platform or AI-first solutions fit that plan, contact the OceSha team.
Define the task, baseline, success event, and review process before expanding your AI assistant.
Measure the right outcomeFrequently asked questions
How often should I review AI assistant performance?
Set a consistent review rhythm based on how often the assistant is used and how frequently your business information changes. Review urgent accuracy problems immediately. The important point is to compare the same outcome and quality measures over time rather than changing the scorecard whenever results fluctuate.
What should count as a successful AI assistant conversation?
Count success when the visitor completes the task defined for that use case, receives an accurate and relevant answer, or reaches the appropriate human path. A response alone is not success, and a long conversation can indicate that the visitor is struggling.
Should an escalation be counted as a failure?
Not automatically. Escalation is successful when the request requires human judgment or information the assistant should not supply, and the visitor reaches the right route efficiently. It is a failure when the assistant should have handled the task but lacked current knowledge or misunderstood the request.
How do I measure an assistant when sales take time?
Use leading indicators tied to the buying journey, such as finding the appropriate information, expressing qualified interest, submitting lead details, or reaching the correct next step. Keep these separate from completed sales so you do not claim an immediate business result that the conversation alone cannot prove.
What if the assistant gives good answers but few people use it?
Check whether visitors can find it, whether its purpose is clear, and whether the selected use case reflects a real need. Low use does not necessarily indicate poor answer quality, but it limits evidence of business value. Avoid expanding until you understand the cause.
Can OceSha AI measure every AI assistant outcome?
OceSha AI supports a broader lifecycle that includes measurement, and course activity contributes to analytics and performance information. For a particular assistant use case, confirm that the available evidence captures your defined task and business outcome; do not assume course or platform activity represents complete assistant performance.
The right question is not whether people are talking to your AI assistant; it is whether they are completing a valuable task with accurate, current information. Define one problem, establish a baseline, inspect real conversations, and connect each interaction to an observable next step. Track failures as seriously as successes, because unresolved questions reveal where the knowledge or workflow needs attention. Expand only after the first use case performs consistently. OceSha AI fits a broader knowledge-to-measurement lifecycle, while assistant performance still requires a scorecard tied to your specific business objective.
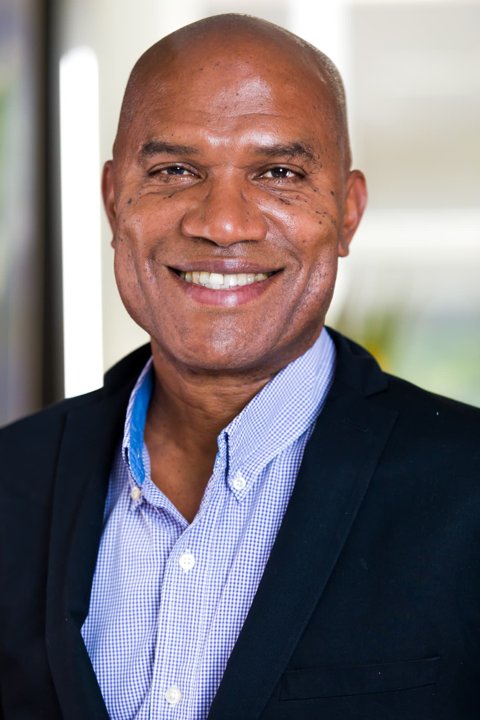
Rohan Hall
Rohan Hall is a technology entrepreneur, AI architect and author with four decades of technology experience, now focused on practical AI across business, education, government and global impact. He founded OceSha Ventures, builds the OceSha AI platform and Lumi, and wrote The Convergence of AI and the Top 10 Emerging Technologies.
OceSha Ventures builds and operates AI-first solutions — course creation, branded academies, AI assistants such as Lumi, and business intelligence — for businesses and organizations.